Model Aggregation
- Latest Model
- Multimodal Model
- Model Market
Token Factory · Inference Acceleration
Train, evaluate, and publish models in Token Factory, then serve them through a low-latency inference engine — one platform from production to runtime.
GPT-4o / Qwen2-72B
Flagship multimodal fusion model
Run to see results here
Token Factory
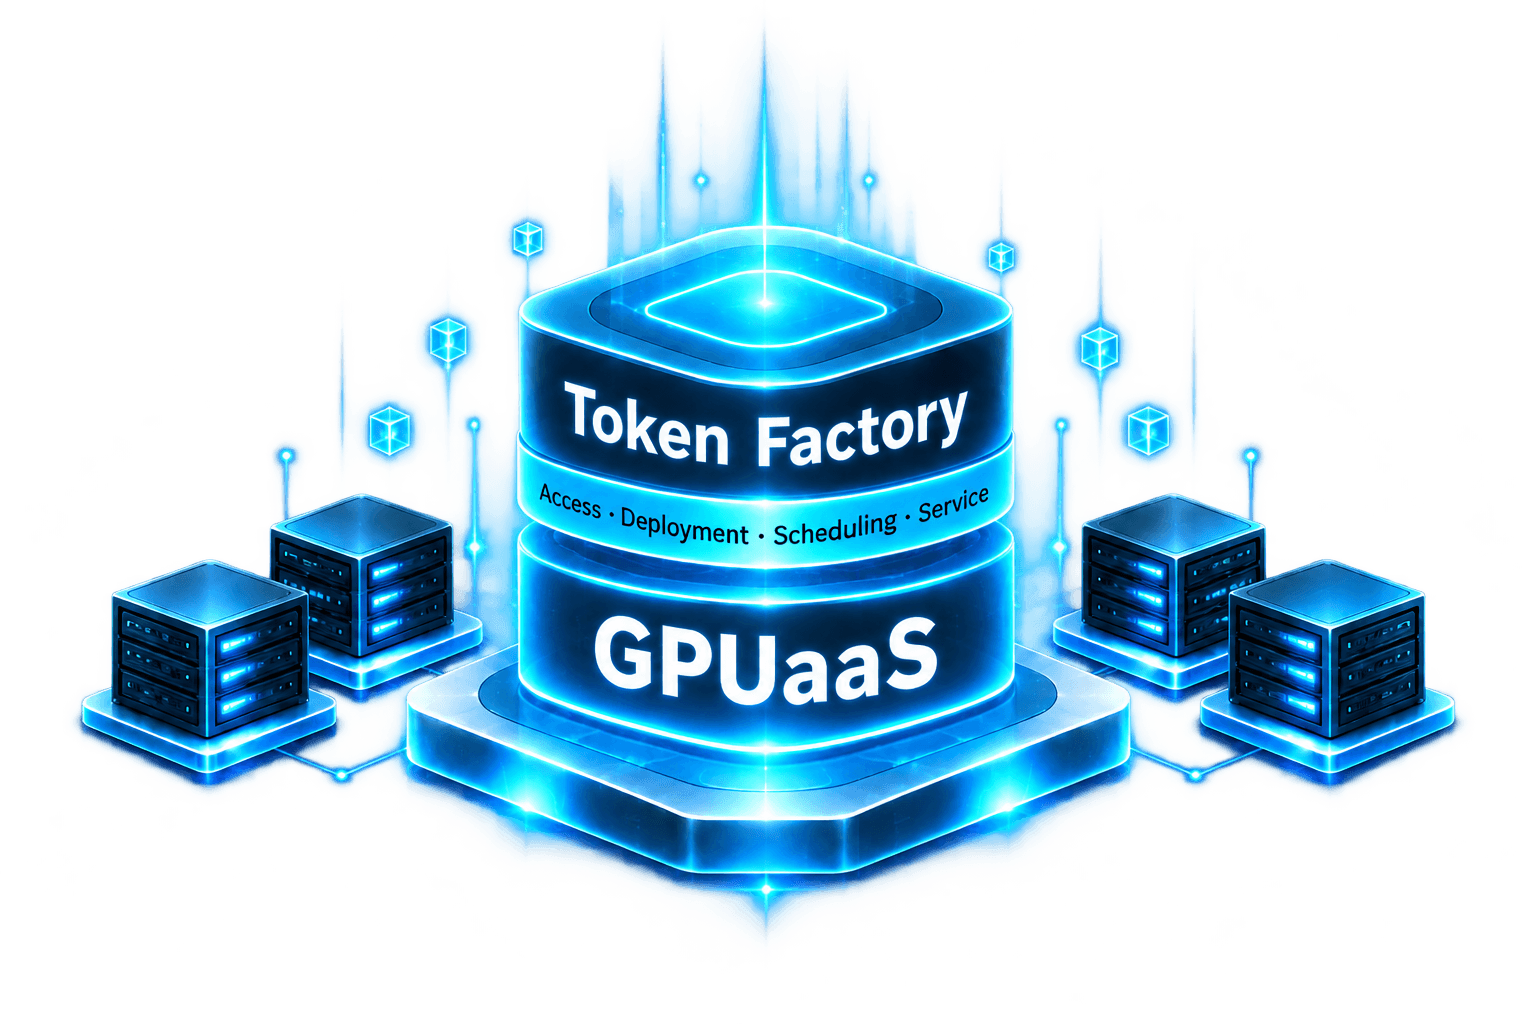
Token Factory stacks model aggregation, smart routing, inference acceleration, and GPUaaS. Access, deploy, schedule, and serve — on self-built clusters, NCP nodes, and elastic cloud.
Core Architecture
Token Factory, inference acceleration, unified APIs, and enterprise Agents — one closed-loop AI platform
End-to-end pipelines for training, fine-tuning, evaluation, and versioned publishing — from dataset to a production-ready checkpoint.
Continuous batching, PagedAttention, quantization, and speculative decoding to cut first-token latency and raise throughput.
Unified access to GPT-4o, Claude 3.5, Qwen2, DeepSeek-V3 and more mainstream LLMs and multimodal models.
Domain RAG knowledge bases and custom Agent development for finance, healthcare, and smart manufacturing.
Model Production & Serving
Produce models in Token Factory, accelerate serving, then expose APIs and Agents on the same platform
Production Pipeline
A unified factory for datasets, training jobs, evaluation reports, and versioned model releases — ready for production serving.
SuperX Platform Core Capabilities
Powered by SuperX platform technology for high-standard, customized enterprise AI infrastructure
Leveraging SuperX elastic scheduling — spin up compute nodes and mainstream models in seconds, dramatically reducing deployment cycles.
Provisioning speed
< 3 sec
Cluster scaling
Minutes
Inference Runtime
A production serving stack that turns published models into low-latency, high-throughput APIs
Continuous batching, PagedAttention, quantization, and speculative decoding cut first-token latency and raise tokens-per-second without changing your API contract.
SuperX Inference Runtime
Continuous batching, paged KV cache, and tensor-parallel serving for long-context LLMs
● Speculative Decoding On
Enterprise Fine-tuning Pipeline
Inject industry terminology, custom Guardrails security fences
Training Active
Breaking general model limits with finance, manufacturing, and healthcare knowledge bases — full pipeline from data cleaning to RLHF.